Full-Stack · 2025
Twitch+
A full-stack app for searching Twitch streams, videos, and clips, with recommendations from your search history and favorites.
Twitch+ media, 2 items. Use the arrow keys to move.
The Twitch logo. Not a screenshot of the app.
I built Twitch+ because looking up a stream, a video, or a clip kept turning into a second search for the thing I had already found. The app is where that search lives, and where the next suggestion comes from the searches I have already run and the favorites I have already saved.
The problem
Twitch is a catalog that does not sit still. A channel is live, then it is not. A clip is easy to lose once the search box is cleared. Search is useful when I already know the name. It is less useful when I am trying to get back to the kind of thing I watched last week, or when a favorite sits in a list that never talks to the next search.
That split is what frustrated me. Search history and favorites were two separate piles, and a recommendation that ignores both of them is just another homepage. It was worth building one account where looking something up, saving it, and being offered the next thing are the same record.
How I built it
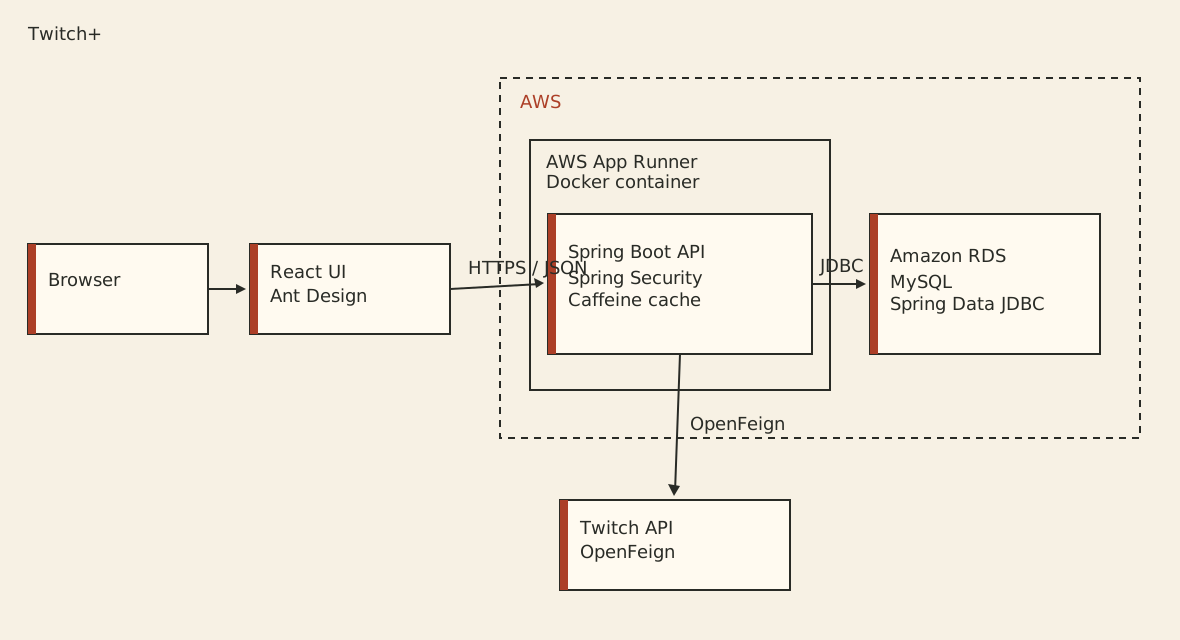
The screen is React 18 and Ant Design. I wanted a search field, a results list, and a favorites view that a person can use without a manual. Ant Design already had the form, the list, and the layout I would otherwise have built by hand, so the interface could stay on the search and not on the chrome.
The API is Spring Boot 3.3.5 on Java 17. History and favorites belong to a person, and they have to still be there after the browser closes, so they live in MySQL on Amazon RDS. Spring Data JDBC is the path from the API to that database. Sign-in is Spring Security, because a history that is not tied to an account is just a log on one laptop.
Recommendations come from that stored history and from those favorites. A search is kept. A favorite stream, video, or clip is kept. The next recommendation is drawn from those two sets. The live catalog stays on Twitch, and the API calls it with OpenFeign.
The same lookup comes back a lot: paging through results, reopening a channel, refreshing a clip. Caffeine sits in front of those hot reads so the repeat does not become another call out to Twitch. The service is packaged with Docker and deployed on Amazon App Runner. The database stays on RDS, outside the container, so a new deploy of the API does not take the history with it.
Challenges and what I learned
The hard split was what to store and what to ask Twitch for. History and favorites are mine. The live catalog is Twitch’s, and it changes underneath a cache. Caching the hot reads is why the app does not call out for every repeat, and it is also why a cached answer can outlive the moment a stream was live. Docker and App Runner kept the deploy to one container. RDS is the piece that has to stay up beside it.