Software · Apr 2024
WikiSearch: Information Retrieval
I built a search box over a crawl of English Wikipedia, ranked with TF-IDF and cosine similarity.
WikiSearch: Information Retrieval media, 2 items. Use the arrow keys to move.
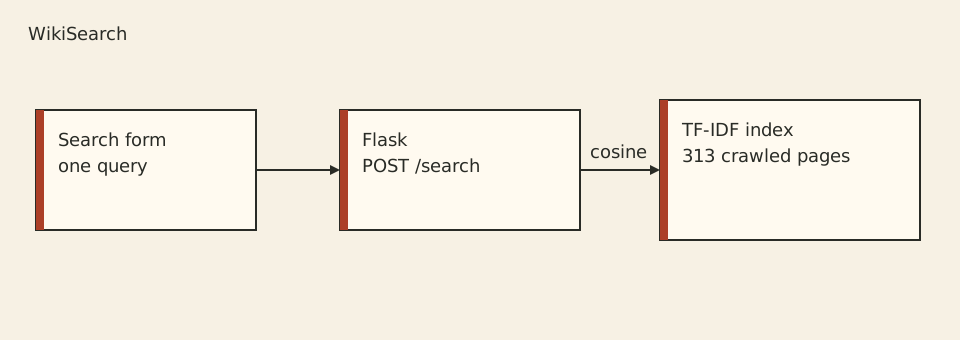
Illustration. Not a screenshot of the app.
I wanted a search I could read end to end: crawl the pages, build the index, rank a query, return the hits. WikiSearch is that box, over a crawl of English Wikipedia, ranked with TF-IDF and cosine similarity.
The problem
A search box over someone else’s index does not show the crawl, the matrix, or why one page outranked another. You get ten blue links and a ranking you cannot recompute. The person it frustrates is the one trying to learn the pipeline, who is handed the last inch of it. It was worth owning the crawl and the index, even if the crawl is a small slice of the encyclopedia.
The cutoff had to be part of the result. An index that pretends to be Wikipedia, and is actually a few hundred pages, should say so by how it was built.
How I built it
A Scrapy spider stays on en.wikipedia.org. It starts from five contents pages and stops at depth 3 or 300 pages, whichever comes first. The crawl that limit produced has 313 pages. Depth and page count are both caps because a contents page fans out, and one of the two will fire first.
The index is a scikit-learn TF-IDF matrix over those pages. A query is transformed with the same vectorizer, so the query lives in the same space as the documents, and ranked by cosine similarity. NumPy is the vector math under that. There is no second embedding model and no second ranking I cannot write down.
The app is Flask. POST /search returns the top 10 as JSON. Ten is the cut on the way out, the same way 300 is the cut on the way in. The box is the Flask page in front of that route.
Challenges and what I learned
The cutoff is part of the result. Depth 3 or 300 pages, whichever comes first, is why the index has 313 pages and not the encyclopedia. A page that never got crawled cannot rank, no matter how good the cosine would have been. I would rather defend a small index I crawled than a ranking over a corpus I cannot list.